As foundThe stock setuid rule matched nothing, and false positives and evasion were not measured
SigmaHQ's Setuid and Setgid rule looks for the literal text chmod u+s. Atomic Red Team's T1548.001 tests run chmod u+xs, and chmod 4755, ug+s or a+s would slip past the same way. Replaying the recorded fixture through both rules (a small script against tripline's own API). The output counts every applicable event; of the 36, two are the attack (the two chmod executions), four are wrapper lines (sudo and dash) that contain the command text, and 30 are unrelated:
Setuid and Setgid                                    applicable  36  matched 0
Setuid or Setgid Bit Set via Chmod (Any Mode Form)   applicable  36  matched 2
The first is the vendored upstream rule, unchanged. The second is the replacement described below. Write-up: docs/findings.md, F-001.
The gate itself, as of v0.2.1, also had gaps that the setuid finding did not show. The rows below are what a check of that version found.
Table, 7 rows: Reading ledger, as found (v0.2.1)
| Check | Expected | Observed | Verdict | Evidence |
|---|---|---|---|---|
| Stock SigmaHQ rule c21c4eaa on the 2 attack events among 36 applicable events | A match on the two chmod executions | 0 of 2 flagged | As found: fail | run 41838714456 failed 2026-11-04 |
| False positives | A count of benign events that match | No benign corpus. A rule that fired on every event would also pass | As found: not measured | v0.2.1 README, limitations |
| Evasion | A count of attack variants that still match | No variants beyond the three command lines of F-001 | As found: not measured | v0.2.1 README, limitations |
| Weights | Each of the 62 weight points traceable to a source | The README says the weights are taken from Red Canary's 2026 ranking, mapped by hand; 17 of the 62 points are for techniques outside that ranking, and no document said which | As found: partial | v0.2.1 README |
| ATT&CK version | The current matrix | Navigator layer on ATT&CK v16, with the tactic Defense Evasion (since split in two) and T1562.008 (since replaced) | As found: out of date | v0.2.1 Navigator layer |
| Workflow supply chain | Third-party actions pinned to a commit | 18 action references pinned to version tags only; zizmor 1.32.0 (auditor persona) reports 42 findings, 19 of them high | As found: unpinned | CHANGELOG 0.3.0, Pipeline hygiene |
| Windows scenarios | Recorded telemetry for all 7 | 3 recorded, 4 pending (T1059.001, T1059.003, T1027, T1053.005); 10 of 14 scenarios passing, 68% weighted coverage | As found: 4 pending | v0.2.1 scorecard |
As leftA replacement rule matches the two chmod runs, and the gaps are now measured
The replacement rule anchors on the chmod binary (and, since the sweep below found the gap, on busybox chmod) and handles symbolic and octal forms. Its two matches on the recorded fixture are the two chmod executions. The upstream rule stays in the rule set, so a future upstream fix is picked up automatically.
Rules written in this repository carry part of the headline. Six rules were written for this project (the setuid replacement, three AWS rules and two Windows rules), and five of the 13 passing scenarios depend on them. Coverage is therefore shown as two figures, always together: 98% of weight points have a passing scenario (61 of 62), but only 52% (32 of 62, 8 scenarios) pass on unmodified SigmaHQ rules alone. tripline computes the split from each expected rule's author field.
Table, 5 rows: The five passing scenarios that need a rule written in this repository (29 of 62 weight points)
| Scenario | Weight | Rule written in this repository | Telemetry |
|---|---|---|---|
| T1078.004 console login without MFA | 10 | AWS Console Login Without MFA | Public CloudTrail replay |
| T1059.003 cmd output redirect | 8 | CMD Output Redirected to a Relative Path From a Suspicious Working Directory; the SigmaHQ rule matched 0 of 11 applicable events | Recorded, run 43090565998 failed 2026-11-11 |
| T1530 S3 bucket exposure | 7 | AWS S3 Bucket Made Public via ACL or Bucket Policy; AWS S3 Bucket Enumeration by IAM User from Non-AWS Tooling | Public CloudTrail replay |
| T1053.005 scheduled task | 2 | Scheduled Task Created With a Command Interpreter or LOLBin Action; the SigmaHQ rule matched 0 of 6 | Recorded, run 43090565998 failed 2026-11-11 |
| T1548.001 setuid and setgid | 2 | Setuid or Setgid Bit Set via Chmod (Any Mode Form); the SigmaHQ rule flagged 0 of the 2 attack events | Recorded, run 41838714456 failed 2026-11-04 |
The two Windows rules were written from the first Windows run's failures and tuned to the command shape of those Atomic tests (F-003); a pass on them shows the rule fits that recording, not that it generalizes. The third newly recorded Windows scenario, T1059.001, passes on the vendored SigmaHQ rule Suspicious Execution of Powershell with Base64 (3 of 22 applicable events, including a real powershell.exe -e command line), after the scenario was narrowed: its download-cradle rule matched 0 of 75 script blocks because no automated atomic runs a cradle, so that half was removed rather than claimed.
Table, 9 rows: Reading ledger, as left (v0.3.0)
| Check | Expected | Observed | Verdict | Evidence |
|---|---|---|---|---|
| Replacement rule on the same 2 attack events | A match on the two chmod executions | 2 of 2 flagged | As left: pass | docs/findings.md F-001 |
| Gate over the committed fixtures | Every scenario with a fixture passes | 13 passed, 0 failed, 1 pending (AWS 4 of 4, Linux 3 of 3, Windows 6 of 7) | As left: pass | run 43100952362 passed 2026-11-11 |
| Weighted coverage, with its split | Both figures stated together | 98% (61 of 62 points); 52% (32 of 62, 8 scenarios) on unmodified SigmaHQ rules alone | As left: split | docs/scorecard.md |
| False positives on a benign corpus | A count | 2 matches from 1 of 6 evaluated rules on 675 events (488 process creations); 20 of 26 rules not evaluated | As left: measured | docs/benign-corpus.md; run 43090057704 passed 2026-11-11 |
| Evasion sweep, 251 command-line variants | A count of variants still caught | 200 caught: setuid 106 of 108, history clearing 71 of 103, cron 23 of 40; 0 of 4 alternative-tool variants | As left: measured | docs/robustness.md |
| Weights | Each point traceable | 45 of 62 points follow Red Canary's public 2026 top 10 (weight = 11 minus rank, seven scenarios); 17 are hand-assigned (seven scenarios) | As left: documented | docs/weights.md |
| ATT&CK version | The current matrix | ATT&CK v20: Defense Evasion split into Stealth and Defense Impairment; T1562.008 became T1685.002; the tactic grid uses the v20 names | As left: v20 | docs/attack-version.md |
| Workflow supply chain | Actions pinned to a commit | All 21 action references pinned to a full commit SHA; zizmor 1.32.0: 42 findings before, 0 after | As left: pinned | CHANGELOG 0.3.0 |
| Windows scenarios | Recorded telemetry for all 7 | 6 of 7 recorded and passing; T1027 still pending (its rule matched 0 of 15 events in the latest recording) | As left: 1 pending | F-003; run 43090565998 failed 2026-11-11 |
The gate over the committed fixtures, run on 2026-11-11 from a fresh clone at tag v0.3.0 (commit a0d6622), Python 3.12.2:
Output, 18 lines: $ tripline replay --all
$ tripline replay --all
[   PASS] t1003-001-lsass-memory-dump (T1003.001, windows) - 70 events
     + 646ea171-dded-4578-8a4d-65e9822892e3  Process Memory Dump Via Comsvcs.DLL  (2/6 applicable events)
     + 5ef9853e-4d0e-4a70-846f-a9ca37d876da  Potential Credential Dumping Activity Via LSASS  (1/4 applicable events)
[PENDING] t1027-obfuscated-powershell-oneliner (T1027, windows) - 0 events
     ~ 44e24481-6202-4c62-9127-5a0ae8e3fe3d  Obfuscated PowerShell OneLiner Execution  (no fixtures)
[   PASS] t1053-003-cron-persistence (T1053.003, linux) - 42 events
     + 6b14bac8-3e3a-4324-8109-42f0546a347f  Scheduled Cron Task/Job - Linux  (1/26 applicable events)
     + 6c4e2f43-d94d-4ead-b64d-97e53fa2bd05  New Cron File Created  (1/3 applicable events)
[   PASS] t1059-003-cmd-suspicious-redirect (T1059.003, windows) - 26 events
     + 467585b7-9de8-40e5-bb2a-6626902ae295  CMD Output Redirected to a Relative Path From a Suspicious Working Directory  (2/11 applicable events)
[   PASS] t1078-004-console-login-without-mfa (T1078.004, aws) - 7 events
     + 3b1f0d2e-7c4a-4d5b-9e8f-2a6c1d0b9f41  AWS Console Login Without MFA  (1/7 applicable events)
     + 8ad1600d-e9dc-4251-b0ee-a65268f29add  AWS Root Credentials  (6/7 applicable events)
[   PASS] t1548-001-setuid-setgid (T1548.001, linux) - 84 events
     + 7f3c2b1a-6d4e-4a9b-9c8d-1e2f3a4b5c6d  Setuid or Setgid Bit Set via Chmod (Any Mode Form)  (2/36 applicable events)
...
gate passed
Trimmed: 6 of the 14 scenarios shown. The full run reports 13 passed, 0 failed, 1 pending, exit code 0.
- passing
- pending, no accepted recording
13 passed, 1 pending, 0 failed
The 14 scenarios: 13 pass and 1 is pending because no Windows recording has been accepted for it. Counts from docs/scorecard.json. 5 of the 13 passes depend on a rule written in this repository.
- caught by an expected rule
- not caught by any expected rule
- One tick is one variant, in the order the sweep generates them.
23 of 40 command-line variants caught (T1053.003)
71 of 103 command-line variants caught (T1070.003)
106 of 108 command-line variants caught (T1548.001); the stock rule caught 0
0 of 4 alternative-tool variants caught (not part of the 251)
Evasion sweep: an expected rule catches 200 of 251 command-line variants of the three Linux attacks, and none of 4 alternative-tool variants. Each tick is one variant, in the order tripline robustness generates them (seed 20261111); re-running the sweep for this page reproduced docs/robustness.md exactly. Hatched ticks are variants no expected rule caught: for cron, crontab given a path outside /tmp/; for history clearing, shell builtins, redirects and whitespace or quoting in the command line; for setuid, a file under /usr/share/doc/ (excluded on purpose) and a renamed copy of chmod. The variant lists are hand-written, replayed as audit events and not executed, and not exhaustive, so a high count is not proof of robustness. The setuid replacement missed busybox chmod u+s until this sweep found it; that is fixed. The other misses are documented in F-004 and not fixed.
- matched no rule
- matched a rule (false positive)
- Each tick is about 10 events; the counts are in the labels.
2 of 675 events matched a rule: New Cron File Created, /etc/cron.daily/chkrootkit
False positives: 2 of 675 benign events matched a rule, both from SigmaHQ's New Cron File Created on a chkrootkit package install. The corpus is one 33-second auditd recording of ordinary work (package installs, git, a build, chmod without setuid, reads of cron files) on one GitHub-hosted Ubuntu runner, run 43090057704 passed 2026-11-11. Only 6 of the 26 rules had applicable events: the 20 Windows and AWS rules were not evaluated, so this is a Linux-only figure, and zero matches on the other five rules does not show they are quiet on a real fleet. The workload deliberately avoids setuid chmod, so it does not test near misses.
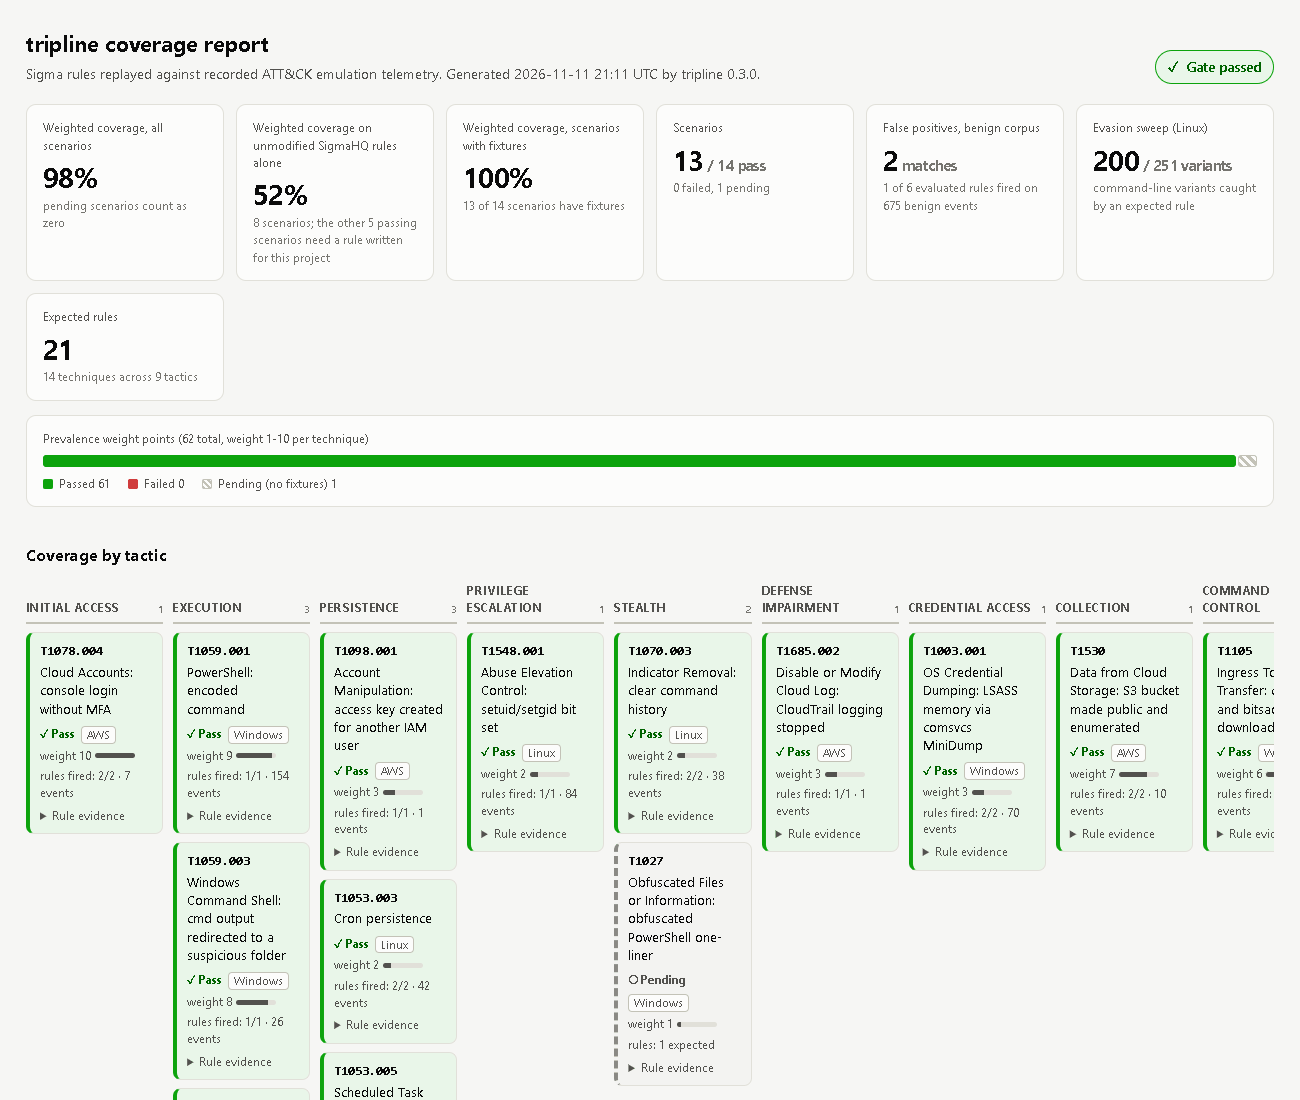
tripline report from the committed scorecard (2026-11-11 21:11 UTC, tripline 0.3.0). Open the live page.Table, 9 rows: Results
| Measure | Value | Source |
|---|---|---|
| Tests | 212 (91% line+branch coverage) | CHANGELOG 0.3.0; run 43100952362 passed 2026-11-11 |
| Scenarios | 14 techniques: 4 AWS (public replay), 3 Linux and 7 Windows (recorded on runners) | docs/scorecard.md |
| Gate | 13 passed, 0 failed, 1 pending | docs/scorecard.json |
| Weighted coverage | 98% of weight points have a passing scenario (61 of 62); 52% (32 of 62) on unmodified SigmaHQ rules alone, from 8 of the 13 passing scenarios | docs/scorecard.json |
| False positives | 2 matches from 1 of 6 evaluated rules, 675 events; 20 of 26 rules not evaluated | docs/benign-corpus.md; run 43090057704 passed 2026-11-11 |
| Evasion sweep | 200 of 251 command-line variants caught; 0 of 4 alternative-tool variants | docs/robustness.md |
| Stock setuid rule | Stock rule: 0 of the 2 attack events among 36 recorded events, and 0 of 108 sweep variants. Replacement: 2 of 2 and 106 of 108 | docs/findings.md F-001, F-004; emulate-linux run 41838714456 failed 2026-11-04 (failed, see limits) |
| Windows fixtures | 6 of 7 scenarios recorded and passing (T1003.001, T1047, T1105, T1059.001, T1059.003, T1053.005) | emulate-windows run 42917025570 failed 2026-11-10 and run 43090565998 failed 2026-11-11 (both show failed, see limits) |
| Release | v0.3.0 | GitHub release |
Technical detailsHow it works
design, implementation points and diagram
The problem
Detection teams count rules and ATT&CK tags. Neither number says whether a rule still fires on the behavior it is named after, and a syntax linter passes rules that never matched anything.
tripline treats a rule like code under test: each scenario names a technique, the Sigma rules that must fire, and recorded telemetry to replay. If an expected rule misses, the exit code is 1. Separately, every rule is replayed over a benign corpus and over generated variants of the attack commands, and the counts are reported.
It is not the first tool to test detections against recorded or generated telemetry: SigmaHQ's regression data, rsigma backtest, SCYTHE's pipeline and Splunk's attack_data each do a version of this. tripline adds a small scenario layer (the technique, the expected rules and the fixture live together in one repository), a plain-Python evaluator that runs offline, and a weighted scorecard. It does not replace any of them (comparison).
What it does
14 scenarios cover 14 ATT&CK techniques across AWS, Linux and Windows. Linux and Windows telemetry comes from Atomic Red Team tests run on GitHub-hosted CI runners; the AWS plane replays public CloudTrail data (Stratus Red Team detonation logs and the flaws.cloud dataset). Rules are compiled to Python and evaluated offline against committed NDJSON, so the whole gate runs in seconds with no SIEM. Output is a JSON scorecard, JUnit XML, an ATT&CK Navigator layer (ATT&CK v20) and a static HTML report.
Coverage is weighted by how common each technique is, so breaking a common technique moves the headline more than breaking a rare one. Weights run from 1 to 10: 45 of the 62 points follow Red Canary's public 2026 top-10 ranking (weight = 11 minus rank, seven scenarios) and 17 are hand-assigned low values for the seven scenarios outside that top 10 (docs/weights.md).
Describe this diagram
- Emulate and record. Atomic Red Team on CI runners; public AWS logs.
- Fixtures committed to the repo. run.ndjson and manifest.json, reviewed by a person.
- Compile Sigma rules to predicates. pySigma parses; tripline walks the condition tree.
- Logsource router. a rule only sees events its logsource matches.
- Replay and score per scenario. weights from technique prevalence.
- Gate: exit 1 if an expected rule misses. scorecard, JUnit, ATT&CK Navigator layer, HTML.
Three implementation points
Compiling the Sigma condition tree into Python predicates
pySigma parses each rule and applies value modifiers. tripline then walks the resulting condition tree and turns every leaf into a closure over an event (tripline/engine/compiler.py): contains, startswith, endswith, all, re, windash, base64offset, cidr, fieldref, numeric comparisons, 1 of and all of. Anything it cannot evaluate raises UnsupportedRuleError, and a scenario whose expected rule failed to compile counts as failed. A gate that cannot evaluate a rule must not pass it. A code review of 0.2.1 found tripline breaking its own rule: timestamp part modifiers such as |hour compiled but never matched. They now evaluate or raise.
Telemetry sliced by run GUID
The Linux workflow wraps every Atomic test in two marker commands, tripline-marker RUN TEST start and ... end. They are ordinary execve events, so attribution lives inside the audit log itself. The collector merges auditd records by serial, hex-decodes EXECVE arguments and keeps only what falls between a pair of markers carrying the run's GUID. Before 0.2.1 a marker from another run in the same log could open or close a window, or leak events from an earlier run; markers with a foreign GUID are now ignored. For cloud data, tripline cloud build shifts eventTime while keeping offsets and appends tripline/<run-guid> to userAgent.
A routing problem is not a missed detection
A rule is evaluated only on events its logsource matches, and results read 1/7 applicable events. If a rule has no applicable events at all, that is reported as a routing problem (wrong product, category or service). 0/7 applicable events (rule did not match) is the real miss. They are separate values of outcome in scorecard.json, the CLI, JUnit and the HTML report, because the fix for each is different. The benign corpus follows the same rule: a rule with no applicable benign events is listed as not evaluated, never as zero false positives.
logsource says which kind of log it applies to.